CloudBlast
Introduction
CloudBlast offers a highly optimized, self-sustained HPC solution to address a very specific need of the OmicsBox community. It runs standard NCBI Blast+ searches directly from within OmicsBox on a dedicated computing cloud, independent of the NCBI servers, providing a high-performance, secure, and cost-optimized service. It consists of a high-performance computing cluster dedicated exclusively to Blast searches.
Cloud Units consumption
CloudBlast runs on OmicsCloud and consumes Cloud Units, like the other cloud alignment tools of the Functional Analysis module (Diamond, CloudBlast Against Custom Database, and InterProScan). All subscriptions include a Cloud Units balance. Consumption is based on the CPU time used, which depends on the number and length of the query sequences, the Blast algorithm (blastx, blastp), the selected database, and the other parameters. The current balance and the consumption of each job can be monitored in View → Cloud Usage. For a full description of Cloud Units, see Cloud Computation and Storage.
To reduce Cloud Units consumption:
- Restrict the search with a taxonomy filter, or blast against a smaller database or an NR subset. The smaller the database, the more sequences can be analysed with a given number of Cloud Units.
- Use the faster
blastx-fastorblastp-fastprograms when high sensitivity is not required.
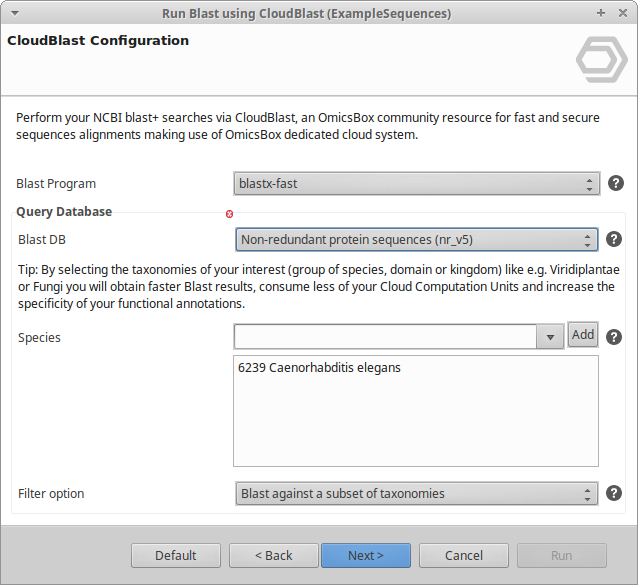
Figure 1. CloudBlast Configuration page.
Run
Select CloudBlast on the first page of the Blast wizard. The wizard provides the following parameters:
-
Blast BlastMode. The Blast algorithm, chosen according to the type of the query sequences. CloudBlast searches protein databases, so the available programs are:
blastp: protein query against a protein database.blastx: nucleotide query, translated in all six reading frames, against a protein database. Used to find the potential protein products of an unknown nucleotide sequence.
Both programs also offer variants:
-fast(blastx-fast,blastp-fast): a faster preset that uses a larger word size, best suited to finding closely related sequences at the cost of sensitivity for distant matches.-short(blastp-short): tuned for short query sequences, using a smaller word size and adjusted scoring.
-
Blast XDb. The protein database to search in, for example nr, SwissProt, or PDB. Default: nr.
- Taxonomy Filter. The taxonomies to blast against. Highly recommended to obtain more specific results and to reduce the computational cost. Filters can be at kingdom, family, genus, or species level.
- Filter Option. How the taxonomy list is used: blast only against the listed taxonomies, or blast against everything except them.
- Disable Taxonomy Filter. When enabled, no taxonomy filter is applied and the search runs against the full database. Available only for v5 databases.
- Blast Expectation Value (e-Value). The statistical significance threshold for reporting matches. Lower values are more stringent and return fewer hits. Default: 1.0E-3.
- Number of Blast Hits. The number of alignments to retrieve (1-100). Default: 20.
- Blast Description Annotator. Finds the best possible description for each sequence from its Blast result. Enabled by default.
- Word Size. The length of the initial word of the local alignment. Smaller values increase sensitivity; larger values increase speed. Default: 6 (for
blastx-fast). - Low Complexity Filter. Applies SEG filtering of low-complexity protein regions before the search. Enabled by default.
- HSP Length Cutoff. The minimum alignment length of an HSP, used to exclude hits with only short local alignments (1-5000). HSPs shorter than this value are discarded, and a hit is excluded when none of its HSPs reaches it. The length is the number of aligned positions in amino acids, gaps included. Hits whose database sequence is shorter than this value are also excluded. Default: 33.
- HSP-Hit Coverage. The minimum percentage of the hit sequence that one of its HSPs must cover, measured over the region of the hit that the HSP aligns to (0-100). Only HSPs that pass the HSP Length Cutoff count. For example, 80 keeps a hit only if at least one of its HSPs spans 80% or more of the hit length. Low values are recommended: most low-coverage hits come from short or partial query sequences matched against longer database sequences. Hits without subject coordinates are not removed by this filter. Default: 0 (no filter).
- Filter by Description. Removes hits whose description contains the given text. Separate several terms with semicolons. Terms are case-sensitive, and a single term is also matched against the hit ID.
On the last wizard page, the results are saved as XML2 files in the selected output folder.
Results
Sequences with hits turn orange and sequences without hits turn dark red in the functional annotation project. The Blast statistics charts, Blast side-panel actions, and the individual Blast result view are described in the Blast Search Results section.