Combined Pathway Analysis
Introduction
Pathway analysis is a useful tool to easily get an overview of the biological mechanisms involved in our data, summarising the information in a way that greatly enhances the capability to interpret the results.
The Combined Pathway Analysis supports four public pathway databases:
- Reactome: a curated database of pathways and reactions in human biology, but containing inferred orthologous reactions for other 15 non-human species. Reactions can be considered as pathways "steps". Reactome defines a reaction as any event in biology that changes the state of a biological molecule.
- Plant Reactome: a resource of plant pathways, curated by Gramene on top of the Reactome data model. It is the recommended choice for plant species, where the coverage of Reactome itself is limited.
- WikiPathways: a community-curated pathway database, openly editable by researchers. Sequences are linked to its pathways through a dedicated BLAST protein database or by matching the sequence names against the identifiers of the pathway elements.
- KEGG: a collection of manually drawn pathway maps representing the knowledge of molecular interaction, reaction, and relational networks for metabolism, genetic information processing, environmental information processing, cellular processes, organismal systems, human diseases, and drug development.
The first step of every pathway analysis is to link the sequences to the pathways present in the database.
The structure can change depending on the source but usually, a given pathway has multiple versions, each one associated with a particular species, and so are all the gene products contained within. This means that to link the sequences to a species-specific pathway, traditionally they had to use the same identifiers. An additional way of linking was to use generic annotation data, like GO terms or enzyme codes.
OmicsBox allows to directly link the sequences to pathways by making use of the platform infrastructure, performing an intermediate step to match a gene product (i.e. protein) to the most probable candidate found in the pathway database. More detailed information can be found in the following subsections.
An optional but highly recommended step is the pathway enrichment analysis to provide statistical significance to the previous linking results. It is run from the side panel of the results, and the information needed can be automatically retrieved from OmicsBox differential expression objects (pairwise or time-course analysis) or manually provided. See the Side Panel Options section for more information.
Finally, the included viewer offers the possibility to inspect in detail an individual pathway by presenting its topology with a layer of additional info containing matched sequences, products, and expression values heatmaps among other things.
Run Pathway Analysis
This functionality can be found under Functional Analysis → Combined Pathways Analysis. It can also be launched from the Pathway Analysis option in the side panel of a functional annotation project; in that case the project is used as input and the input page is skipped.
The wizard starts with a page to select the pathway databases (Figure 1), followed by the input page and one configuration page for each selected database. The pages of the databases that are not selected are skipped. The last page is the general CloudSync Data Handling page (see Cloud Sync).
Database Selection
Select the databases to include in the analysis: Reactome, Plant Reactome, WikiPathways and KEGG. At least one database must be selected, and the selection is remembered for the next run. KEGG is only available with a subscription that includes it; otherwise its option is disabled.
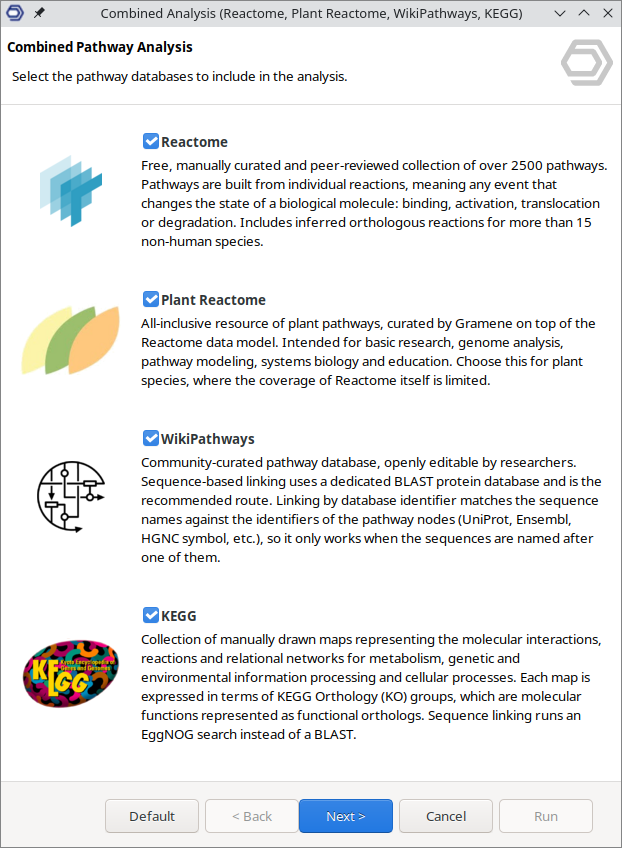
Figure 1: Database Selection
Input options
- Sequences (.box, .fasta, .annot): a file containing sequence info (.fasta, .box), GO / EC annotations (.annot, .box) or both (.box) is required. Depending on the available data some linking options might not be considered in the analysis.
Differential expression data and the pathway enrichment analysis are not part of the wizard. Once the pathways have been identified, they are added from the side panel of the results with Add Diff. Expression, Fisher's Exact Test and Gene Set Enrichment Analysis (see Side Panel Options).
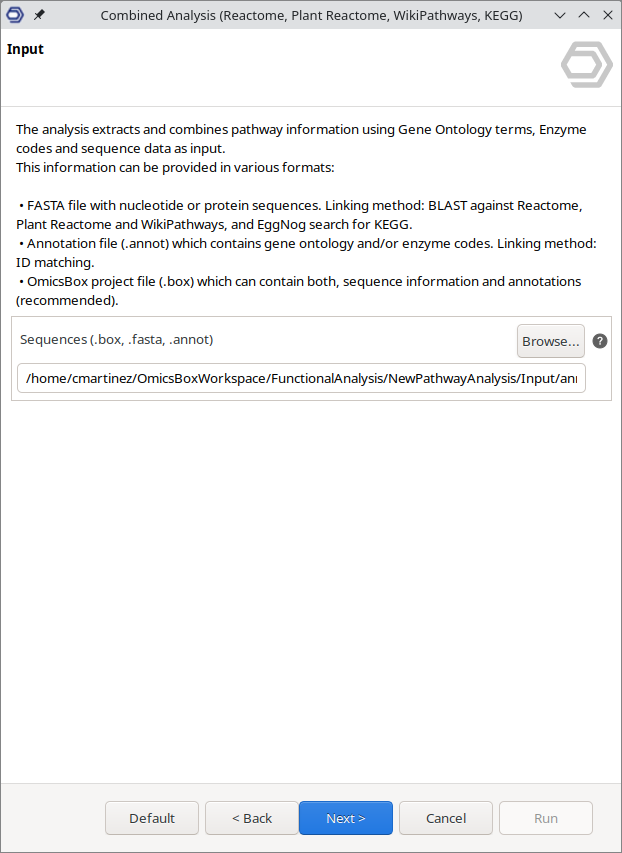
Figure 2: Input Options
Configuration Reactome Pathway Analysis
-
Pathway Linking Options:
- Run Blast to link via Protein IDs: requires having sequence data in our input. This will run a BLAST against a custom database containing the sequences of all available Uniprot proteins associated with a pathway in Reactome. Note: this will consume cloud units.
- Link with GeneOntology Terms: requires having annotated GO terms for each feature. This will link to pathways directly using the GO BP, then a GO MF to associate to the reactions contained in it.
-
Filtering Options: the View species coverage link at the top of this group opens a table comparing, for each species, the coverage of the BLAST protein database with the GO annotation coverage of the pathways. Giving priority to a taxon only helps when that organism is represented in the BLAST database.
-
Keep Most Specific Pathways: Reactome pathways are organized hierarchically, so the obtained table could contain too many general entries that might not be of interest. When enabled, only the most specific pathways found are kept and their parents are discarded whenever possible. Two limits apply:
- A parent pathway is discarded only when no sequence needs it as its most specific pathway. If a single sequence still justifies it, the parent is reported for the whole project.
- Pathways linked through GO annotation are kept regardless of the hierarchy, because that linking already selects pathways by GO term specificity.
-
Give Priority to Taxon: Reactome can contain different species-specific versions of the same pathway (inferred by orthology). When enabled, the selected taxon is used in two ways:
- If a pathway has been found for different species, only the version of the selected taxon is kept if it has been found; otherwise, all of them are kept. This applies whether or not Keep Most Specific Pathways is enabled.
- In the BLAST top hit selection, the hits are scanned choosing the top priority taxon over the other ones or, if not found, the first one. This selection takes place over the hits meeting the e-value and coverage criteria.
-
Top Priority Taxon: organism to give priority. Reactome is primarily based on human reactions but it contains pathways for other species that might be closer to the dataset used. See the setting "Give Priority to Taxon" for more information.
- Blast Expectation Value: the statistical significance threshold for reporting matches against the database.
- Minimum Hit Coverage (%): discard BLAST hits in which no HSP covers at least this percentage of the matched database protein, so that matches covering only a small fragment of the reference protein are removed. Only HSPs of at least 33 aligned positions are considered. Low values are recommended, since most low-coverage hits come from short or partial query sequences.
- Include Categories: by selecting only the categories of interest the final number of pathways reported is reduced, which could have a positive impact on the multiple testing correction performed on the enrichment analysis.
-
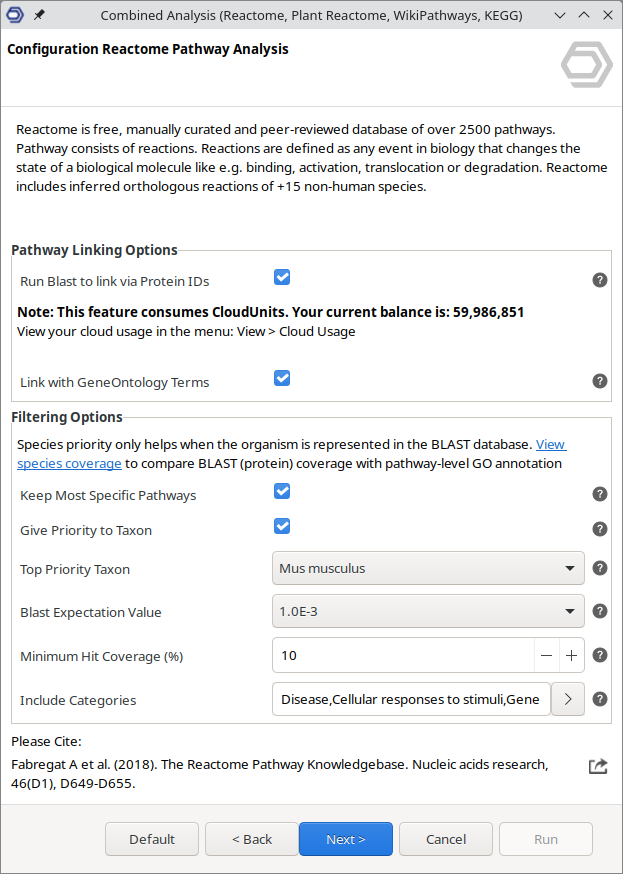
Figure 3: Reactome Database
Configuration Plant Reactome Pathway Analysis
-
Pathway Linking Options:
- Run Blast to link via Protein IDs: requires having sequence data in our input. This will run a BLAST against a custom database containing the sequences of all available Uniprot proteins associated with a pathway in Plant Reactome. Note: this will consume cloud units.
- Link with GeneOntology Terms: requires having annotated GO terms for each feature. This will link to pathways directly using the GO BP, then a GO MF to associate to the reactions contained in it.
-
Filtering Options: the View species coverage link at the top of this group opens a table comparing, for each species, the coverage of the BLAST protein database with the GO annotation coverage of the pathways. Giving priority to a taxon only helps when that organism is represented in the BLAST database.
-
Keep Most Specific Pathways: Plant Reactome pathways are organized hierarchically, so the obtained table could contain too many general entries that might not be of interest. When enabled, only the most specific pathways found are kept and their parents are discarded whenever possible. Two limits apply:
- A parent pathway is discarded only when no sequence needs it as its most specific pathway. If a single sequence still justifies it, the parent is reported for the whole project.
- Pathways linked through GO annotation are kept regardless of the hierarchy, because that linking already selects pathways by GO term specificity.
-
Give Priority to Taxon: Plant Reactome can contain different species-specific versions of the same pathway (inferred by orthology). When enabled, the selected taxon is used in two ways:
- If a pathway has been found for different species, only the version of the selected taxon is kept if it has been found; otherwise, all of them are kept. This applies whether or not Keep Most Specific Pathways is enabled.
- In the BLAST top hit selection, the hits are scanned choosing the top priority taxon over the other ones or, if not found, the first one. This selection takes place over the hits meeting the e-value and coverage criteria. The Plant Reactome BLAST database does not contain sequences for all organisms: if the selected taxon is not represented in it, this setting only affects the choice between the species versions of a pathway, not the BLAST top hit selection.
-
Top Priority Taxon: organism to give priority. See the setting "Give Priority to Taxon" for more information.
- Blast Expectation Value: the statistical significance threshold for reporting matches against the database.
- Minimum Hit Coverage (%): discard BLAST hits in which no HSP covers at least this percentage of the matched database protein, so that matches covering only a small fragment of the reference protein are removed. Only HSPs of at least 33 aligned positions are considered. Low values are recommended, since most low-coverage hits come from short or partial query sequences.
- Include Categories: by selecting only the categories of interest the final number of pathways reported is reduced, which could have a positive impact on the multiple testing correction performed on the enrichment analysis.
-
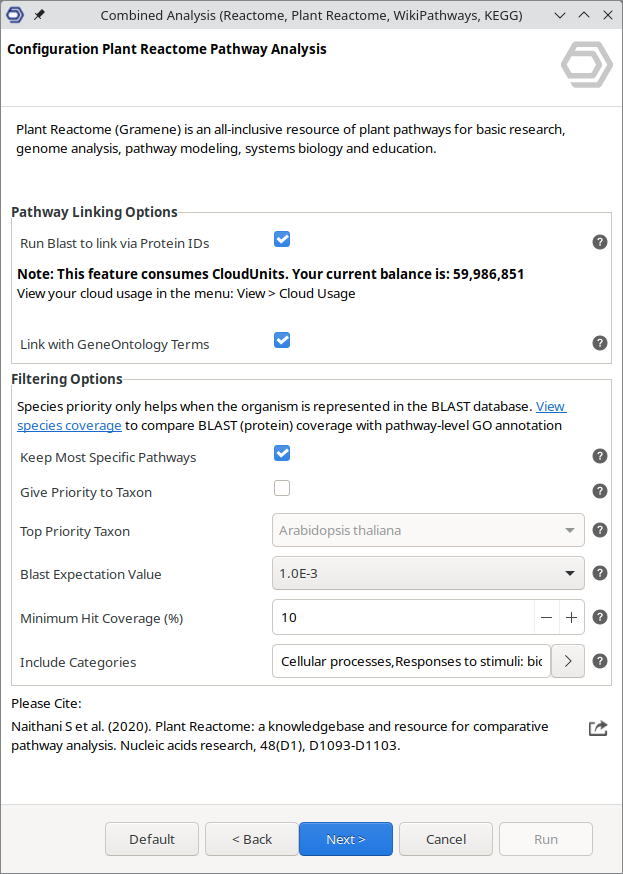
Figure 4: Plant Reactome Database
Configuration WikiPathways Pathway Analysis
-
Pathway Linking Options:
- Run Blast to link via Protein IDs: requires having sequence data in our input. This will run a BLAST against a custom database containing the sequences of the Uniprot proteins found in WikiPathways pathways. This is the recommended linking method. Note: this will consume cloud units.
- Link by database identifier: link to pathways by matching each sequence name against the identifiers of the pathway elements (UniProt, Ensembl, HGNC symbol, etc.). Gene Ontology terms are not used, so this option only finds links when the sequences are named after one of these identifiers.
-
Filtering Options: the View species coverage link at the top of this group opens a table comparing, for each species, the coverage of the BLAST protein database with the term annotation coverage of the pathways. Giving priority to a taxon only helps when that organism is represented in the BLAST database.
- Give Priority to Taxon: when enabled, the BLAST top hit results will be scanned, choosing the top priority taxon over the other ones or, if not found, it will choose the first one. Note that this selection process takes place over hits meeting the specified e-value and coverage criteria.
- Top Priority Taxon: organism to give priority. See the setting "Give Priority to Taxon" for more information.
- Blast Expectation Value: the statistical significance threshold for reporting matches against the database.
- Minimum Hit Coverage (%): discard BLAST hits in which no HSP covers at least this percentage of the matched database protein, so that matches covering only a small fragment of the reference protein are removed. Only HSPs of at least 33 aligned positions are considered. Low values are recommended, since most low-coverage hits come from short or partial query sequences.
- Include Categories: by selecting only the categories of interest the final number of pathways reported is reduced, which could have a positive impact on the multiple testing correction performed on the enrichment analysis.
WikiPathways pathways are not organized in the hierarchy of species-specific versions used by Reactome, so the Keep Most Specific Pathways option is not available for this database.
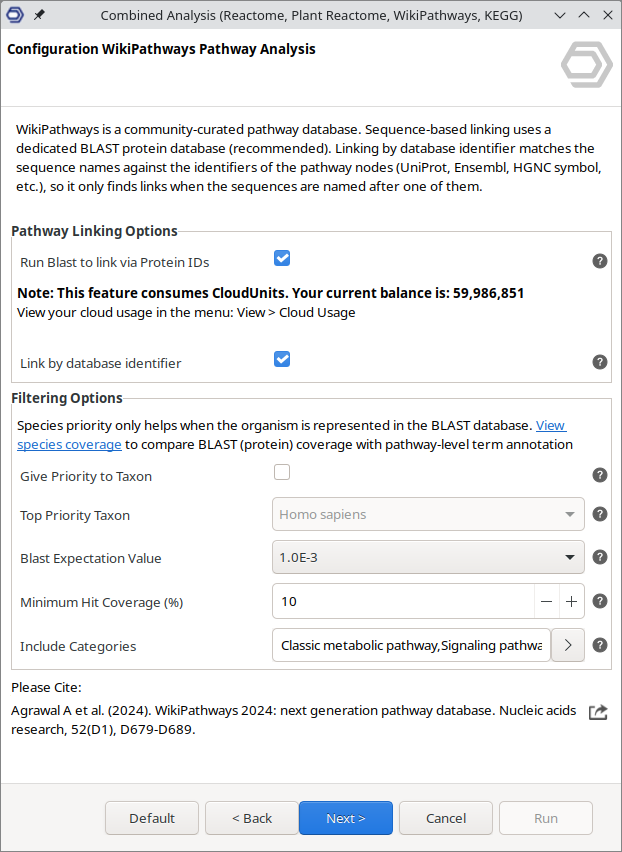
Figure 5: WikiPathways Database
Configuration KEGG Pathway Analysis
-
Pathway Linking Options:
- Link KEGG Orthologs via EggNog: use the sequence data to retrieve the KEGG orthologs with eggNOG-mapper (see Functional Annotation with EggNOG Mapper). The search is configured in the EggNog Configuration group.
- Link via Enzyme Codes: direct link to pathways using the sequence annotated enzymes codes.
-
Filtering Options:
- Include Categories: by selecting only the categories of interest the final number of pathways reported is reduced, which could have a positive impact on the multiple testing correction performed on the enrichment analysis.
-
EggNog Configuration: only available when Link KEGG Orthologs via EggNog is enabled.
- EggNog Input Type: how the sequences are processed. Proteins: amino acid sequences are searched with BLASTp. CDS: coding sequences are translated to proteins and searched with BLASTp. Genes/Contigs (default): nucleotide sequences are searched in all six reading frames with BLASTx. The input type must match the input sequences (protein or nucleotide); otherwise the wizard shows an error. Sequences longer than 2.5 Mb are skipped.
- EggNog Taxonomic Scope: restrict the orthologs used to transfer the annotations to a taxonomic clade. By default, Adjust Automatically (auto) determines the scope for each sequence from its best matches. Select a specific clade when the taxonomic origin of the sequences is known.
- EggNog GO Evidence: which Gene Ontology terms are transferred from the orthologs. Experimental uses only terms supported by experimental evidence codes. Non-Electronic (default, recommended) uses all evidence codes except electronic annotation.
- EggNog Minimum Hit e-Value: the e-value threshold for the seed ortholog matches of the homology search. Lower values are more stringent.
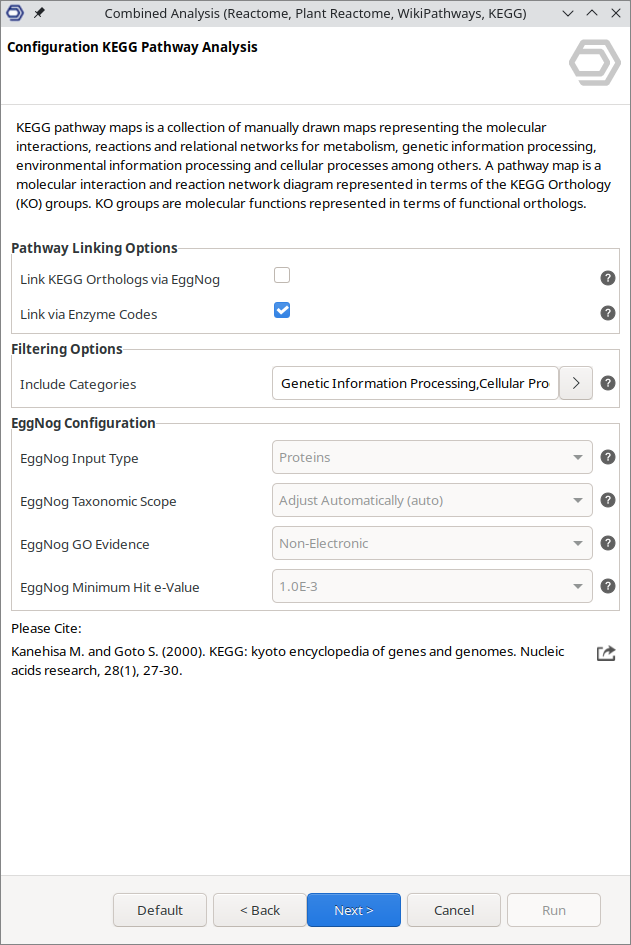
Figure 6: KEGG Database
Analysis Results
Results Table
After identifying the pathways associated with the sequences a table will open (figure 7). The pathways of all the selected databases are listed in the same table, and the Database column shows the source of each one (Reactome, Plant Reactome, WikiPathways or KEGG). If it contains enrichment statistical information, it will be automatically sorted using first the absolute GSEA NES or, if not available, Fisher's p-value.
The number of sequences linked to a pathway is usually correlated with the size of the pathway: the bigger it is, the bigger the chance of having sequences linked from the original dataset. That is why sorting by enrichment statistical significance is preferred over the total number of sequences (column #Seqs).
Under some circumstances, on Reactome and Plant Reactome pathways linked through GO terms the total number of sequences (column "#Seqs") associated to a particular BP term (pathway) might be considerably higher than the sequences actually linked to the reactions contained in it (MF term); in those cases the column "#Linked Seqs", hidden by default, might provide a better representation. For WikiPathways and KEGG, which do not use GO linking, both columns have the same value.
Other hidden columns show how the sequences were linked to entities: "#Seqs with ET (BLAST)" counts the sequences linked through BLAST (Reactome, Plant Reactome and WikiPathways), and "#Seqs with ET (Term)" counts the sequences linked by database identifier (WikiPathways).
For sequences which are not present in the provided differential expression results, the value in the column "#Diff. Expr Seqs" may be "."; this signifies that, although there are sequences associated with the given pathway, none of them have any expression data and are therefore not differentially expressed.

Figure 7: Pathways Results Table
Context Menu
- Show Pathway Diagram: open the pathway viewer.
- Show Pathway Data: open a table with one row for each pathway and linked sequence of the selection, including whether the sequence is differentially expressed and the terms that link it to the pathway.
-
Retrieve Selection Mapping Data of:
- Linked sequences: sequences found in the selected pathways.
Note: for Reactome and Plant Reactome pathways containing GO terms this will not count the sequences associated to the BP term. - Differentially expressed linked sequences: differentially expressed sequences found in the selected pathways.
- Found GO CC terms: only for Reactome and Plant Reactome pathways, return found GO CC terms. The list might be empty even if GO MF have been found since they are not a requirement in the matching process.
- Found GO MF terms: only for Reactome and Plant Reactome pathways, return found GO MF terms.
- Found entities: only for Reactome, Plant Reactome and WikiPathways pathways, return found entities. For Reactome and Plant Reactome the entities are Uniprot proteins; for WikiPathways they are the identifiers of the pathway elements, which can come from different databases (UniProt, Ensembl, NCBI Gene, etc.).
- Found enzymes: only for KEGG pathways, return found enzyme codes.
- Found KEGG orthologs: only for KEGG pathways, return found KEGG orthologs.
- Linked sequences: sequences found in the selected pathways.
Side Panel Options
- Summary Report: report containing the most important findings of the analysis, including linked pathways per database and number of sequences. If enrichment data is available, it will show top 10 enriched pathways. Information about the original input data and parameters is also displayed.
- Add Diff. Expression: add differential expression data to a pathways analysis project, overriding the previous one if exists. The supported results are pairwise analyses from edgeR, DESeq2 and NOISeq, and time course analyses from maSigPro. Results from limma are not supported.
Loading an OmicsBox differential expression analysis object adds useful information to the pathway object:
- Experimental design information
- Count values
- Differentially expressed features
By providing this data some other features are enabled, like automatically calculating a pre-ranked list for GSEA enrichment analysis or selecting the test-set features in Fisher's choosing by tag. Also, the pathway viewer is enhanced by being able to show expression heatmaps.
Loading new expression data clears the previous enrichment results. To remove the current expression data, as well as the enrichment information generated with it, check the option "Remove current expression data".
- Fisher's Exact Test: perform a pathway enrichment analysis using Fisher's Exact Test. For a detailed description of the test, see Fisher's Exact Test.
In a Fisher's pathways enrichment, the reference set used are all those sequences associated with a pathway; enable "Count only seqs with expression" to use only those with expression data. The test-set can be manually provided ("Use custom test-set genes") or automatically generated with the selected tags if a differential expression analysis has been added to the project. By default all the available tags are selected; only tags with at least one sequence linked to a pathway are listed. The test is one-tailed by default. Every pathway keeps its p-value and FDR, and those with FDR ≤ 0.05 are tagged as over- or under-represented.
Enable the option "Open Enrichment Projects" (default) to show the enrichment table project for each database. * Set Over/Under Tags: change the criteria to consider pathways as enriched according to the Fisher's Exact Test results. Mode selects the p-value or the adjusted p-value (default), and pathways below the Cut-off (default 0.05) are tagged as over- or under-represented. * Gene Set Enrichment Analysis: perform a pathway enrichment analysis using GSEA. For a detailed description of GSEA, see Gene Set Enrichment Analysis.
The Gene Set Database generated for GSEA pathway enrichment contains every sequence associated with each pathway. However, only those records present also in the ranked list will actually be used.
The pre-ranked list can be manually provided or automatically generated from the differential expression analysis added to the project. For edgeR and DESeq2 results the formula used to rank each sequence is:
Rank = sign(logFC) * - log10(p-value)
NOISeq results are ranked with their own ranking statistic. Time course results are not supported, as they do not provide logFC information.
By default the settings are set to 1000 permutations, maximum gene set size of 500 and minimum gene set size of 15. Enable the option "Open Enrichment Projects" to show the enrichment table project for each database, with access to the detailed GSEA plots.
Note that when performing pathway analysis on transcripts, rather than genes, enrichment analysis should not be used. This is because both Fisher's Exact Test as well as GSEA expect their input sequences to be independent of each other, which is not the case for transcripts belonging to the same gene.
-
Charts: create charts summarizing the results.
- Basic Stats: one bar chart with the number of found and enriched pathways grouped by database.
- Category Distribution: one bar chart per database with the number of pathways found and enriched for each category.
- Fisher's Enrichment Stats: one bubble plot per database, showing the Fisher's enriched pathways with rich ratio (differentially expressed sequences/linked sequences ratio) as X axis, FDR as color value and number of sequences as point size. Needs expression data loaded into the pathway project.
- GSEA Enrichment Stats: one bubble plot per database, showing the GSEA enriched pathways with rich ratio (differentially expressed sequences/linked sequences ratio) as X axis, NES as color value and number of sequences as point size. Needs expression data loaded into the pathway project.
-
Export Data: export the information contained within each row that is not directly visible on the table (associated terms, sequences…). It provides different configuration options to format the output:
- Data to include: optional columns to append. Note that some of them will be empty for some tables.
- Include counters: include the number of terms found for each column.
- Column separator: character to separate the columns.
- Item separator: character to separate the items inside each column.
-
Grouping:
- One Sequence per Row: one line for each found sequence.
- One Item per Row: one line for each term found.
- One Pathway per Row: one line for each pathway.
-
Export Pathway Diagrams: export all pathway diagrams from the current results table using the default pathway viewer configuration. Since this action exports diagrams for all pathways in the table, the resulting files may require significant storage space. To export a subset, first select the relevant rows and export the selection to a new project, then export the diagrams from the filtered dataset.
-
Search Function: an autocomplete search widget to search in the information contained inside pathways. In order to work first a text needs to be entered in the input, then an option must be selected in the suggestion panel before clicking "Search". The clear text button will only remove the input text but not reset the table filtering. Currently wildcards are not supported.

Figure 8: Side Panel Options
Pathway Viewer
If the enrichment analysis provides statistical significance about the identified pathways, the pathway viewer helps us to visualize the reactions or interactions between elements in one pathway.
This functionality can be found in the context menu (right-clicking) of each pathway's results table row, under the option "Show Pathway Diagram".
Pathway Map
This is the visual representation of the pathway map (figure 9). Reactome and Plant Reactome diagrams share the same viewer, while WikiPathways and KEGG have their own. In the top-left corner the following configuration settings can be found:
- Center Pathway: zoom the pathway diagram to fill the available space. Some Reactome and Plant Reactome pathways might make use of more general diagrams, so using this option in those cases will center around the subset of elements to consider (sub-pathway).
- Toggle Minimap: display a minimap view representing the visible diagram portion over the total.
- Zoom In and Zoom Out: change the zoom level of the diagram.

Figure 9: Pathway Map
Labels and background coloring
Elements in the pathway are drawn differently depending on the type of map. For Reactome, Plant Reactome and WikiPathways, the entity nodes have a static text that never changes, whereas KEGG displays a dynamic term at the center of each box, dependent on the current settings and the sequences found, so the label change after toggling one or multiple entries is expected behavior for that type of map.
In the default map view mode, the background coloring will use a solid color, assigned to each term or reaction. Because the number of available colors in the palette is limited, repeated colors can be present in medium pathways.
After enabling map expression view mode, a heatmap will be used instead of the color if the element has at least one sequence with expression data. This is the default view mode when expression data is available.
Tool Tip
The tool tip shows details of each element of a pathway (figure 10). The content is different for each pathway database and in every case the information displayed will follow the current filtering settings (i.e. enabled reactions). Each list shows up to 30 items.
On Reactome and Plant Reactome pathways the tool tip contains:
- Title: type of the element, as described by the diagram file.
- Subtitle: name of the element, usually matching the rendered text.
- Reaction(s): reactions associated to the element; one element can be shared with multiple reactions, each with its own color.
- Entities in this node: when BLAST is used as linking option, the sequence is associated to one protein and the participation of said protein in a reaction can be pointed to a particular set of elements (nodes). If the tooltip's element contain this specific information, that will be the one displayed, distinguished by having a green background.
- GO/Entities in this reaction: gene ontology only allows to associate a sequence with a reaction, not to specific elements in it. When no "Entities in this node" is available, the terms associated to the reaction will be shown instead, distinguished by having a blue background.
- Associated Expression in this node: only with differential expression data. Will show a heatmap of the sequences associated to this node.
On WikiPathways pathways the tool tip has the same structure, with interactions instead of reactions:
- Title: type of the element, as described by the diagram file.
- Subtitle: name of the element, usually matching the rendered text.
- Interaction(s): interactions associated to the element.
- Entities in this node: entities linked to the element, through BLAST or by database identifier.
- GO/Entities in this reaction: when no "Entities in this node" is available, the terms associated to the interaction are shown instead.
- Associated Expression in this node: only with differential expression data. Will show a heatmap of the sequences associated to this node.
When an element has no interaction data, the tool tip lists the entities linked to the element and their associated sequences instead.
On KEGG pathways the tool tip contains:
- Title: type of the element, can be "ortholog", "enzyme" or both, depending if the pathway has KO and EC versions in KEGG.
- Subtitle: names and descriptions of currently enabled terms associated to the element.
- Associated Reactions: in KEGG reactions are only available for metabolic pathways.
- EC/KO in this node: terms associated to the element, only visible for pathways with reactions.
- Associated Terms: if no reactions are available, all the terms associated to the element are shown.
- Associated Expression: only with differential expression data. Will show a heatmap of the sequences associated to this node.

Figure 10: Tool Tip
Side Panel
Configuration
- Search: select one of the elements from the drop-down to show only entries associated with it.
-
View mode: change the information shown in the sidebar panel (figure 11). Available modes are slightly different between the viewers:
Database View modes Reactome, Plant Reactome Group by sequences, Group by reactions, Expression WikiPathways Group by sequences, Group by interactions, Expression KEGG Group by sequences, Group by reactions, Group by ortholog groups, Expression - Group by sequences: show one entry per term, these may be KO (Kegg ortholog) and EC (enzyme code) in KEGG, ET (entity: Uniprot protein) and GO (gene ontology) in Reactome and Plant Reactome, and ET (entity: identifier of a pathway element) in WikiPathways.
- Group by reactions: show one entry per reaction; note that in KEGG, reactions are only available in metabolic pathways.
- Group by interactions: only available on WikiPathways pathways, show one entry per interaction.
- Group by ortholog groups: only available on KEGG pathways, show one entry per box (containing related orthologs).
- Expression: show a heatmap containing all the expression values present in the pathway, matching the current filtering settings.
-
Paint expression data in the map: only with expression data. Activate map expression view mode.
- Show only results with differential expression data: only with expression data. Limit entries to those that have at least one differentially expressed sequence.
-
Advanced heatmap options:
- Paint heatmap header using the factor: only with expression data. Select how the samples should be ordered or grouped in the heatmap; it can be a factor or two-factor combination of the available in the experimental design table.
- Paint heatmap values using the attribute: only with expression data. Select which value (z-score or log CPM) should be used for coloring the heatmap.
- Use mean values in heatmaps: only with expression data. Use the average of the samples included in the selected condition instead of individual values.
- Cluster heatmap results: use hierarchical clustering to sort the rows of the heatmap to group sequences by similar expression patterns.
- Show attributes table instead of heatmap: instead of a color heatmap, display a summary table with the attributes (i.e. FDR, logCPM or others).
- Re-calculate attributes instead of avg: only with expression data. When using mean values in the heatmap, instead of calculating the average of the individual selected attribute (z-score/log CPM) for the corresponding samples, it calculates the average of the counts for those samples and then the real log CPM or z-score.
- Scale the heatmap color range using individual factors: only with expression data. To create the heatmap color scale, the range is set considering the sequences found in the whole project, not only the current pathway, and using individual samples excluding outliers; by enabling this setting, the range will be based on the selected factor, which means that instead of taking the individual sample values, it will be based on the average.

Figure 11: Side Panel - configuration
Information Panel
The information panel shows different data depending on the selected "View mode". Common functionalities for panel entries are the "ID" button to create an ID list of the sequences associated to the entry, and a toggle button to paint it or not on the pathway map.
-
"Group by sequences" view mode: it can show up to 2 blocks:
- "Linked Enzyme Sequences" and/or "Linked KO Sequences" for KEGG pathways.
- "Linked MF Sequences" and/or "Linked Entity Sequences" for Reactome and Plant Reactome pathways.
- "Linked entities" for WikiPathways pathways (a single block).
-
In the sequences grouping mode, there will be a row for each found term (enzyme code, kegg ortholog, GO molecular function term or entity/protein) with the following information:
- Sequences associated to the term.
- Type, ID and name of the term. Entity rows show a BLAST and/or ID badge, indicating whether the entity was linked through BLAST or by database identifier.
- Reactions (if any) associated to the term. Placing the cursor over the icon will highlight the reaction in the pathway map.
- Associated Expression: heatmap of the associated sequences having expression data.
-
"Group by reactions" view mode: only available for Reactome, Plant Reactome and KEGG metabolic pathways. In this grouping mode there will be a row for each reaction with the following information:
- Sequences associated to the reaction.
- Type, ID and name of the reaction.
- Associated terms (enzymes, entities…)
- Associated expression: heatmap of the associated sequences having expression data.
-
"Group by interactions" view mode: only available for WikiPathways pathways. There will be a row for each interaction, with the same information as in the "Group by reactions" mode.
-
"Group by ortholog groups" view mode: only available with KEGG pathways. There will be a row for each ortholog group (a box in the pathway map) with the following information:
- Sequences associated to the ortholog group.
- Type, ID and name of all the enzymes or orthologs associated to the group.
- Associated expression: heatmap of the associated sequences having expression data.
-
"Expression" view mode: in this mode a general heatmap including all expression data found in the pathway is rendered, including a summary containing the number of found tags for each tag (up, down, none...).

Figure 12: Side Panel - information panel
Pathway Hierarchy
Contains the category tree of the current pathway.

Figure 13: Side Panel - pathway hierarchy
Additional Information
Example Datasets can be found within the Functional Analysis Module Example Data: https://resources.biobam.com/omicsbox/example_data/version_2_0_0/FunctionalAnalysis.zip
OmicsBox Engine
This tool can be run from the command line via the OmicsBox Engine.
Command: omicsbox pathway-analysis [options]
Input constraint: provide exactly one of:
--i-local-project,--i-project-file,--i-expression-result.
Inputs
| Flag | Type | Required | Description |
|---|---|---|---|
--i-local-project |
file | Yes | Sequence Project (.box) |
--i-project-file |
file | Yes | Sequences (.box, .fasta, .annot) |
--i-expression-result |
file | Yes | Differential Expression Data (.box) |
Parameters
| Flag | Type | Default | Range / Candidates | Required | Description |
|---|---|---|---|---|---|
--reactome-db |
boolean | true | No | Run Reactome Pathway Analysis | |
--kegg-db |
boolean | true | No | Run KEGG Pathway Analysis | |
--reactome-most-specific |
boolean | true | No | Keep Most Specific Pathways | |
--use-expression-result |
boolean | false | No | Add Pairwise Expression Data | |
--reactome-prioritize-species |
boolean | false | No | Give Priority to Taxon | |
--blast-expect-value |
enum | 1.0E-3 | 1000105 |
No | Blast Expectation Value |
--reactome-sequence-linking |
boolean | true | No | Run Blast to link via Protein IDs | |
--reactome-annotation-linking |
boolean | true | No | Link with GeneOntology Terms | |
--kegg-sequence-linking |
boolean | true | No | Link KEGG Orthologs via EggNog | |
--kegg-annotation-linking |
boolean | true | No | Link via Enzyme Codes | |
--gramene-sequence-linking |
boolean | true | No | Run Blast to link via Protein IDs | |
--gramene-annotation-linking |
boolean | true | No | Link with GeneOntology Terms | |
--gramene-db |
boolean | true | No | Run Gramene Pathway Analysis | |
--gramene-expect-value |
enum | 1.0E-3 | 1000105 |
No | Blast Expectation Value |
--gramene-prioritize-species |
boolean | false | No | Give Priority to Taxon | |
--gramene-most-specific |
boolean | true | No | Keep Most Specific Pathways | |
--run-gsea |
boolean | true | No | Gene Set Enrichment Analysis | |
--run-fisher |
boolean | true | No | Fisher's Exact Test | |
--reactome-priority-species |
enum | Homo sapiens | Bos taurusCaenorhabditis elegansCanis familiaris |
No | Top Priority Taxon |
--gramene-priority-species |
enum | Arabidopsis thaliana | Actinidia chinensisAegilops tauschiiAmborella trichopoda |
No | Top Priority Taxon |
--kegg-categories |
enum (multiple) | Genetic Information Processing, Cellular Processes, Environmental Information Processing, Organismal Systems, Human Diseases, Drug Development, Metabolism | Genetic Information ProcessingCellular ProcessesEnvironmental Information ProcessingOrganismal SystemsHuman DiseasesDrug DevelopmentMetabolism |
No | Include Categories |
--reactome-categories |
enum (multiple) | Disease, Cellular responses to stimuli, Gene expression (Transcription), Protein localization, Drug ADME, Autophagy, Mycobacterium tuberculosis biological processes, Reproduction, Metabolism of RNA, Immune System, Organelle biogenesis and maintenance, Hemostasis, Digestion and absorption, Circadian Clock, DNA replication and repair, Signal Transduction, Extracellular matrix organization, Vesicle-mediated transport, DNA Replication, Chromatin organization, Metabolism, Programmed Cell Death, Muscle contraction, Drosophila signaling pathways, Cell-Cell communication, Cell Cycle, DNA Repair, Innate Immune System, Neuronal System, Metabolism of proteins, Developmental Biology, Sensory Perception, Transport of small molecules | DiseaseCellular responses to stimuliGene expression (Transcription) |
No | Include Categories |
--gramene-categories |
enum (multiple) | Cellular processes, Responses to stimuli: biotic stimuli and stresses, Responses to stimuli: abiotic stimuli and stresses, Metabolism and regulation, Circadian rhythm, Growth and developmental processes | Cellular processesResponses to stimuli: biotic stimuli and stressesResponses to stimuli: abiotic stimuli and stressesMetabolism and regulationCircadian rhythmGrowth and developmental processes |
No | Include Categories |
--kegg-egg-nog-input-type |
enum | genes | proteinscdsgenes |
No | EggNog Input Type |
--kegg-egg-nog-taxonomic-scope |
enum | auto | auto84992225057 |
No | EggNog Taxonomic Scope |
--kegg-egg-nog-target-orthologs |
enum | all | allone2onemany2oneone2manymany2many |
No | EggNog Target Orthologs |
--kegg-egg-nog-go-evidence |
enum | non-electronic | experimentalnon-electronic |
No | EggNog GO Evidence |
--kegg-egg-nog-blast-expect-value |
enum | 1.0E-3 | 1000105 |
No | EggNog Minimum Hit e-Value |
Parameter relationships
| Flag | When | Effect | Affected flags |
|---|---|---|---|
--reactome-db |
false |
disables | --reactome-most-specific, --reactome-prioritize-species, --blast-expect-value, --reactome-sequence-linking, --reactome-annotation-linking, --reactome-categories |
--use-expression-result |
true |
enables | --i-expression-result |
--reactome-prioritize-species |
true |
enables | --reactome-priority-species |
--reactome-sequence-linking |
false |
disables | --blast-expect-value |
--gramene-sequence-linking |
false |
disables | --gramene-expect-value |
--gramene-db |
false |
disables | --gramene-sequence-linking, --gramene-annotation-linking, --gramene-expect-value, --gramene-prioritize-species, --gramene-most-specific, --gramene-categories |
--gramene-prioritize-species |
true |
enables | --gramene-priority-species |
Note:
--kegg-db,--kegg-sequence-linking,--kegg-annotation-linking,--run-gsea,--run-fisher,--kegg-categories,--kegg-egg-nog-input-type,--kegg-egg-nog-taxonomic-scope,--kegg-egg-nog-target-orthologs,--kegg-egg-nog-go-evidence,--kegg-egg-nog-blast-expect-valueare context-dependent — they apply, and their valid values are determined, only for certain input configurations.Global options (
--local-folder,--cloud-folder,--output-format,--config,--detach,--verbose, …) are shared by every Engine tool — see the OmicsBox Engine reference.
References
- Agrawal A et al. (2024). WikiPathways 2024: next generation pathway database. Nucleic acids research, 52(D1), D679-D689.
- Altschul, S.F., Gish, W., Miller, W., Myers, E.W. & Lipman, D.J. (1990) "Basic local alignment search tool." J. Mol. Biol. 215:403-410.
- BioBam Bioinformatics. (2019). OmicsBox - Bioinformatics made easy. Retrieved March 3, 2019, from https://www.biobam.com/omicsbox.
- Fast genome-wide functional annotation through orthology assignment by eggNOG-mapper. Jaime Huerta-Cepas, Damian Szklarczyk, Lars Juhl Jensen, Christian von Mering and Peer Bork. Submitted (2016).
- eggNOG 4.5: a hierarchical orthology framework with improved functional annotations for eukaryotic, prokaryotic and viral sequences. Jaime Huerta-Cepas, Damian Szklarczyk, Kristoffer Forslund, Helen Cook, Davide Heller, Mathias C. Walter, Thomas Rattei, Daniel R. Mende, Shinichi Sunagawa, Michael Kuhn, Lars Juhl Jensen, Christian von Mering, and Peer Bork. Nucl. Acids Res. (04 January 2016) 44 (D1): D286-D293. doi: 10.1093/nar/gkv1248
- Fabregat A et al. (2018). The Reactome Pathway Knowledgebase. Nucleic acids research, 46(D1), D649-D655.
- Kanehisa M. and Goto S. (2000). KEGG: kyoto encyclopedia of genes and genomes. Nucleic acids research, 28(1), 27-30.
- Naithani S et al. (2020). Plant Reactome: a knowledgebase and resource for comparative pathway analysis. Nucleic acids research, 48(D1), D1093-D1103.